A new study published in the American Journal of Roentgenology shows that deep learning-generated segmentations produce radiomic features with significant bias and poor agreement compared to manual segmentations, potentially affecting the accuracy and generalizability of radiomics models used in medical imaging analysis.
- Poor Agreement: DL models showed poor or fair agreement in 20-86 radiomic features across datasets, with MRI datasets showing the worst performance
- Systematic Bias: Between 36-92 features demonstrated bias when using DL-generated segmentations versus manual methods
- Reduced Accuracy: Models trained on DL-generated features achieved worse accuracy (mean 0.05-0.12) compared to manual segmentation approaches
- Generalizability Issues: DL-derived models showed worse generalizability across all tested models (mean 0.10-0.17)
- Research Recommendation: Researchers should clearly describe segmentation methodology and recognize how segmentation differences can confound radiomics results
Deciding between manual and deep learning (DL)-derived segmentation could affect the downstream effects of radiomics models on CT and MRI, according to research published October 14 in the American Journal of Roentgenology.
DL-derived segmentation led to varied performance and agreement on abdominal CT and MRI in both children and adults, wrote a team led by Jonathan Dudley, PhD, from Cincinnati Children’s Hospital Medical Center in Ohio.
“These findings demonstrate that radiomic features extracted from DL-generated segmentations commonly exhibit limited agreement with, and presence of bias relative to, features derived from manual segmentations,” the Dudley team wrote.
DL models address the labor-intensive nature of manual segmentation when extracting radiomic features from imaging. This advancement automates whole-organ segmentation, which could make way for large-scale feature extraction.
Dudley and colleagues noted that differences in radiomic outputs compared with manual segmentations could affect performance and generalizability of models using DL-generated segmentations.
The researchers focused their study on agreement of radiomic features extracted from manual and DL-generated segmentations. They also compared model performance between these feature extraction approaches.
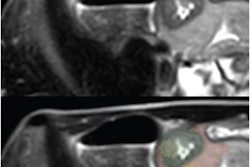
The study used datasets from earlier studies. These included axial contrast-enhanced abdominal CT exams from 139 children with normal pancreas (dataset A) and axial T2-weighted abdominal MR sequences from 64 children and young adults [ages 7 to 24 years) with autoimmune liver disease (dataset B).
Automated segmentation for dataset A used included three publicly available DL models: MRSegmentator, TotalSegmentator’s default CT task, and PaNSegNet’s CT model. For dataset B, three publicly available DL models were used: MRSegmentator, TotalSegmentator’s total_mr task, and NV-Segment-CTMR’s MRI_BODY model.
The researchers observed similar performance across the models for each dataset.
For dataset A, 30 features on MRSegmentator, 32 features on TotalSegmentator, and 30 features on PaNSegNet showed poor or fair agreement. And 36, 47, and 20 features showed bias, respectively.
For dataset B, 81 features on MRSegmentator, 71 features on TotalSegmentator, and 86 features on NV-Segment-CTMR demonstrated poor or fair agreement. And 88, 92, and 81 features showed bias, respectively.
Models trained with DL-generated segmentations features achieved worse accuracy for MRSegmentator (mean, 0.05) and PaNSegNet (mean, 0.12). However, the team observed no significant difference for TotalSegmentator (mean, -0.01).
The DL-derived models also showed worse generalizability for MRsegmentator (mean, 0.15), TotalSegmentator (mean, 0.10), and PaNSegNet (mean, 0.17).
These results could have ramifications for planning large-scale radiomic analyses, the study authors wrote.
“Accordingly, researchers developing radiomic models should clearly describe segmentations methodologies, and those seeking to employ, validate, or compare radiomic models should recognize how methodologic differences in segmentation could confound results,” they added.
Read the full study here.